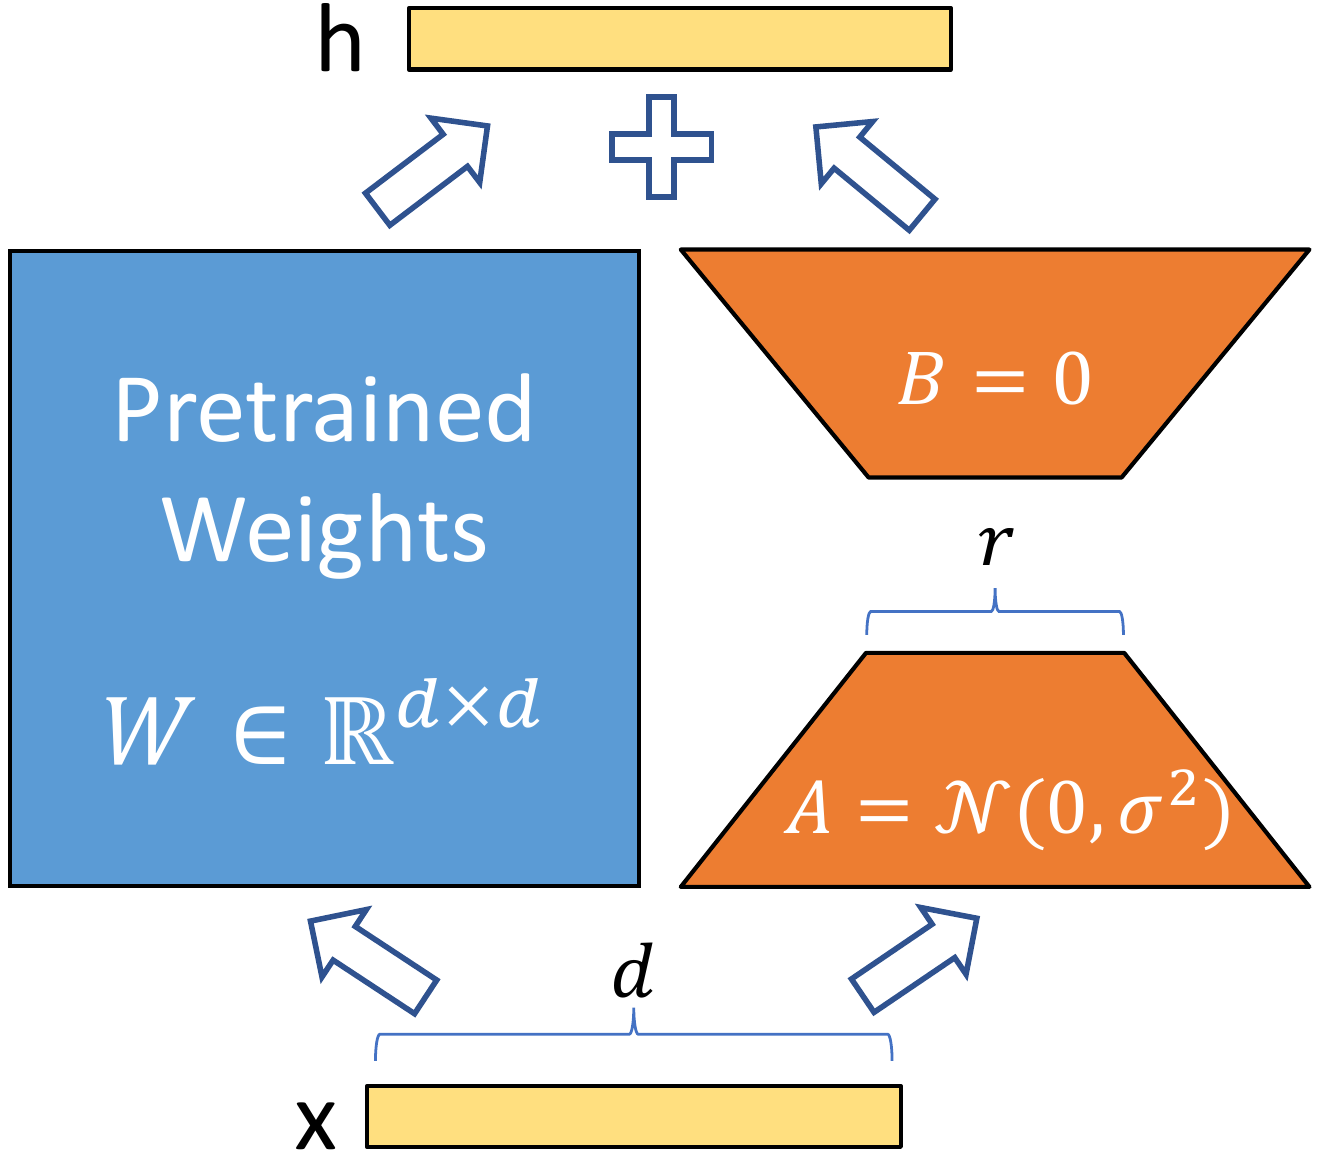
Figure 6. The paper's Figure 1: "Our reparametrization. We only train A and B."
Adapting a frozen model to a new task by training small added modules.
On this page
How do you teach a large model a new task without retraining the whole thing?
Full fine-tuning updates every parameter of a transformer, a stack of blocks where the positions of a sequence first exchange information and then each position is processed on its own, and keeps one full copy per task. This page uses RoBERTa-base as its example model: 12 layers with hidden size 768 and 125 million parameters, the learned numbers that make up its weights (BERT-base has the same shape and 110 million).
Worse, Adam, the optimizer that runs training, keeps extra state for every parameter:
And the model learns the new task and starts forgetting the old ones. That is catastrophic forgetting.
Adapters do the opposite: freeze the big model, add small trainable modules, and train only those (Figure 1).
Adapters train like ordinary fine-tuning, on every step of the new task's data, and the state a task leaves behind is its adapter (Figure 2). The gradient still has to pass through the frozen backbone to reach the adapters, and at serving time LoRA, the second method here, folds away.
The original idea (Houlsby et al. 2019) is simple. Each transformer layer has an attention block, where each position mixes in information from the other positions, and a feed-forward block, which processes each position on its own. After each one you insert a small two-layer MLP (multilayer perceptron) with a bottleneck: the hidden state, the vector that carries one position through the layer, is 768 numbers wide, and the adapter projects it down to 64 numbers and back up to 768.
Figure 3. Only the orange adapters learn; blue stays frozen.
With adapters the base stays frozen and a new task never revisits the old ones.
Transferring BERT (Bidirectional Encoder Representations from Transformers, a large pretrained language model) to GLUE (a standard suite of language-understanding tests), adapters land within 0.4% of full fine-tuning while adding only 3.6% parameters per task, against 100% for fine-tuning; the paper finds the same pattern across 26 text classification tasks.
The listing is the whole module; input and output are both hidden_dim wide.
import torch.nn as nn

class SimpleAdapter(nn.Module):
    def __init__(self, hidden_dim, bottleneck_dim):
        super().__init__()
        h, m = hidden_dim, bottleneck_dim
        self.down_proj = nn.Linear(h, m)
        self.relu = nn.ReLU()
        self.up_proj = nn.Linear(m, h)

    # x: (batch, seq, hidden_dim)
    def forward(self, x):
        z = self.relu(self.down_proj(x))
        # residual: frozen x plus update
return x + self.up_proj(z)down_proj to the bottleneck, ReLU (negatives become 0, positives pass), up_proj back up.forward adds the input back, so the frozen signal passes untouched if the adapter does nothing.A wider bottleneck adds capacity and parameters; a narrower one is cheaper but can underfit. On GLUE the paper picked 8, 64 or 256 per task (256 for the large MNLI, 8 for the small RTE), and fixing 64 cost 0.4 points on average.
The parameter count, with a hidden size of 768 and a bottleneck of 64; a bias is one learned number added to each output of a projection, on top of its weights.
Training two percent of the model leaves the other 98 percent where pretraining put it. That is why the model does not forget.
Training is the usual loop with one filter, so the optimizer keeps no state for the backbone. The learning rate is a placeholder.
for name, param in model.named_parameters():
    # all else frozen
    param.requires_grad = "adapter" in name
ps = model.parameters()
trainable = [p for p in ps if p.requires_grad]
optimizer = torch.optim.AdamW(trainable, lr=1e-4)Figure 5. Every trainable parameter sits in the two projections.
down_proj, relu and up_proj in order.return in SimpleAdapter.LoRA (low-rank adaptation, Hu et al. 2022) looks at what fine-tuning does to a weight matrix. It starts from the pretrained weight W and ends with W plus a big dense update, dense meaning its entries are filled in rather than mostly zero. The useful part of that update lives in a tiny subspace, a low dimensional slice of all possible updates, so LoRA learns it as two skinny matrices multiplied together.
Figure 6. The paper's Figure 1: "Our reparametrization. We only train A and B."
Reparametrization means writing the trained weight as the frozen W plus the learned BA detour, so the update lives in the two small matrices.
The r brace between the slabs is the rank, the entire budget of new parameters.
A starts as small random numbers from a bell curve centered at 0; Figure 6 names that curve N with spread σ (not the ReLU σ of Section 1), set by the code's * 0.01. B starts at zeros, so at step one the side path adds nothing to the pretrained model.
The code wraps a frozen linear layer self.linear with the side path through A then B.
import torch
import torch.nn as nn

class LoRALinear(nn.Module):
    def __init__(self, linear, rank=8, alpha=16.0):
        super().__init__()
        # frozen W
        self.linear = linear.requires_grad_(False)
        k = linear.out_features
        d = linear.in_features
        a0 = torch.randn(rank, d) * 0.01
        self.A = nn.Parameter(a0)
        # BA = 0 at start
        self.B = nn.Parameter(torch.zeros(k, rank))
        self.scale = alpha / rank

    # x: (..., d) -> (..., k)
    def forward(self, x):
        side = x @ self.A.T @ self.B.T
return self.linear(x) + self.scale * sideBefore serving, fold BA into W once and call the plain layer, so inference costs nothing extra:
# (k, r) @ (r, d) = (k, d)
delta = lora.scale * (lora.B @ lora.A)
with torch.no_grad():
    lora.linear.weight += delta
# serve this plain layer
merged = lora.linearIn practice LoRA wraps the query and value projections of each attention block and leaves the rest frozen. A projection is a learned matrix that turns each position into a new vector: the query says what a position is looking for, the key what it advertises, and the value what it passes along (see Attention). The listing wraps them in RoBERTa-base.
# RobertaModel, all frozen
model.requires_grad_(False)
for block in model.encoder.layer:
    attn = block.attention.self
    attn.query = LoRALinear(attn.query)
    attn.value = LoRALinear(attn.value)
# later modules stay trainableThe rank r sets those numbers. A task close to what the model already does, such as sentiment classification, needs little rank; a task far from it, such as reasoning or code, can keep using more.
Raising r gives the update more directions in which to change W, at r·(d + k) trainable numbers per matrix; lowering it can miss part of the update, and r = 0 is the frozen model. At r = min(d, k) the update is as free as full fine-tuning; LoRA's RoBERTa runs use r = 8 (its Table 9). In LoRA Table 6 (GPT-3 175B) r of 1 or 2 is enough, and WikiSQL and MultiNLI stay flat up to 64.
scale in the code) scales BA. Raising α makes every step change the update BA more, much like a larger learning rate; lowering it shrinks every update, and at α = 0 the model stays frozen. Because α acts like the learning rate, the paper sets α to the first r it tries and does not tune it (the paper's Section 4.1).At r = 64 LoRA trains as many parameters as a bottleneck adapter, still only a sixth of the dense matrix. Start at 8, go up only if the loss says so.
Figure 9. Illustrative curves; only the hard task keeps gaining.
A quarter of one percent of the model, and it usually lands within a point of full fine-tuning on classification-style tasks.
After the merge in the folding listing, the model runs exactly as fast as the original; bottleneck adapters cannot merge, because their nonlinearity blocks it, so their extra layers stay forever.
Adapters are already small. Compacter (Karimi Mahabadi et al. 2021) asks whether the adapter's own matrices can be cheaper. Compacter uses the Kronecker product: instead of storing a big dense matrix, store two small factors A and B (Compacter's own, not LoRA's) and let their product stand in for it.
In the Kronecker product A ⊗ B, each element of A scales a whole copy of B.
One factor pair is enough to build a full adapter matrix:
Only the factors are stored, 8·8 + 96·8 = 832 numbers, against 768·64 = 49,152 for the dense matrix.
Compacter builds each adapter matrix as a sum of these products:
Training only 0.047% of the model's parameters, it matches full fine-tuning on GLUE and beats it on SuperGLUE, GLUE's harder successor suite, and in low-resource settings, where only a little task data is available.
The listing uses one product with a full B; Compacter sums n of them and makes each B rank one. The big matrix is never built.
def kron_linear(x, A, B):
    # x @ (A ⊗ B) without building A ⊗ B
    # A: (m, n), B: (p, q), x: (batch, m*p)
    m, p = A.shape[0], B.shape[0]
    X = x.view(-1, m, p)
    Y = A.T @ X @ B
    # (batch, n*q)
return Y.reshape(x.shape[0], -1)The cost is that the weight matrix is no longer fully free; it has to factor this way.
SST-2 (the Stanford Sentiment Treebank: movie-review sentences labeled positive or negative) accuracy for RoBERTa-base, as reported in the LoRA paper's Table 2. BitFit trains only the bias terms; AdapterDrop (Rücklé et al. 2021) is a bottleneck adapter that drops the adapters in the lowest layers. The full fine-tuning, BitFit and AdapterDrop numbers are ones LoRA took from prior work (Figure 12).
LoRA trains 0.24 percent of the parameters and matches full fine-tuning on this task.
LoRA and Compacter are not the only way to keep the update small.
| Method | What trains | When it helps |
|---|---|---|
| Prompt tuning (Lester et al. 2021) | A short soft prompt: learned vectors placed in front of the real words | Very large frozen models; it closes the gap to fine-tuning as models exceed billions of parameters |
| Prefix tuning (Li and Liang 2021) | Learned key and value vectors set in front of the sequence in every attention layer | Generation tasks on large frozen models |
| BitFit (Ben Zaken et al. 2022) | Only the bias terms | The smallest budget: 93.7% on SST-2 with 0.1M parameters in LoRA Table 2 |
A LoRA fine-tune is an ordinary training loop on a model whose chosen projections were swapped for LoRALinear, with an optimizer that holds only A, B and the task head. Microsoft's loralib packages the same steps: build the layer with lora.Linear (shown for one projection), freeze everything else in model, and save only the LoRA weights.
import torch
import loralib as lora

# replaces nn.Linear
q_proj = lora.Linear(768, 768, r=8)
lora.mark_only_lora_as_trainable(model)
ps = model.parameters()
trainable = [p for p in ps if p.requires_grad]
optimizer = torch.optim.AdamW(trainable, lr=1e-4)
# ... the usual training loop ...
# A and B only
sd = lora.lora_state_dict(model)
torch.save(sd, "lora.pt")strict=False.model.eval() merges BA into W and model.train() splits it out again, so evaluation in the middle of training is safe.qkv projection needs lora.MergedLinear with enable_lora, or each part gets one shared update instead of its own.Adapters shrink what is trained; Quantization, storing each weight with fewer bits, shrinks the frozen 98 percent that still sits in memory. QLoRA (Dettmers et al. 2023) combines the two: it trains LoRA adapters through a frozen base quantized to 4 bits, enough to fine-tune a 65B-parameter model on one 48 GB GPU. The attention projections LoRA wraps are taught in Attention.
Parameter-Efficient Transfer Learning for NLP. ICML 2019. arXiv:1902.00751
LoRA: Low-Rank Adaptation of Large Language Models. ICLR 2022. arXiv:2106.09685
The Power of Scale for Parameter-Efficient Prompt Tuning. EMNLP 2021. arXiv:2104.08691
Prefix-Tuning: Optimizing Continuous Prompts for Generation. ACL 2021. arXiv:2101.00190
BitFit: Simple Parameter-efficient Fine-tuning for Transformer-based Masked Language-models. ACL 2022 (arXiv 2021). arXiv:2106.10199
AdapterDrop: On the Efficiency of Adapters in Transformers. EMNLP 2021. arXiv:2010.11918
Compacter: Efficient Low-Rank Hypercomplex Adapter Layers. NeurIPS 2021. arXiv:2106.04647
QLoRA: Efficient Finetuning of Quantized LLMs. 2023. arXiv:2305.14314